Speedata’s Analytics Processing Unit (APU)
Up to 100x performance gains with Speedata APU
Speedata APU for Apache Spark
Hardware-accelerated analytics built for the modern data stack
Apache Spark has become the backbone of large-scale data processing, but even at scale, it is still constrained by general-purpose CPUs and GPU trade-offs that were never designed specifically for analytics workloads.
Speedata changes that.
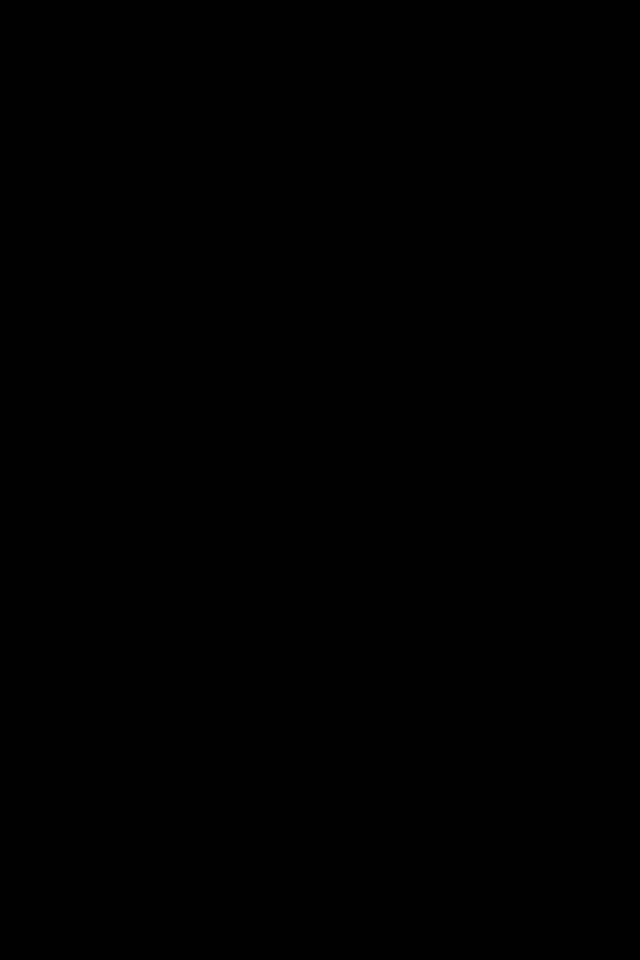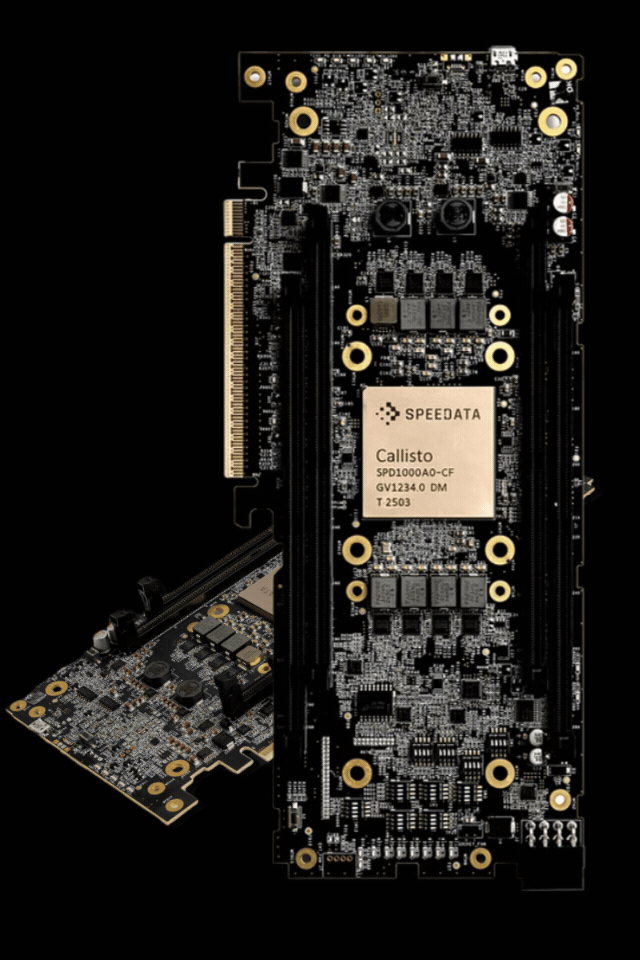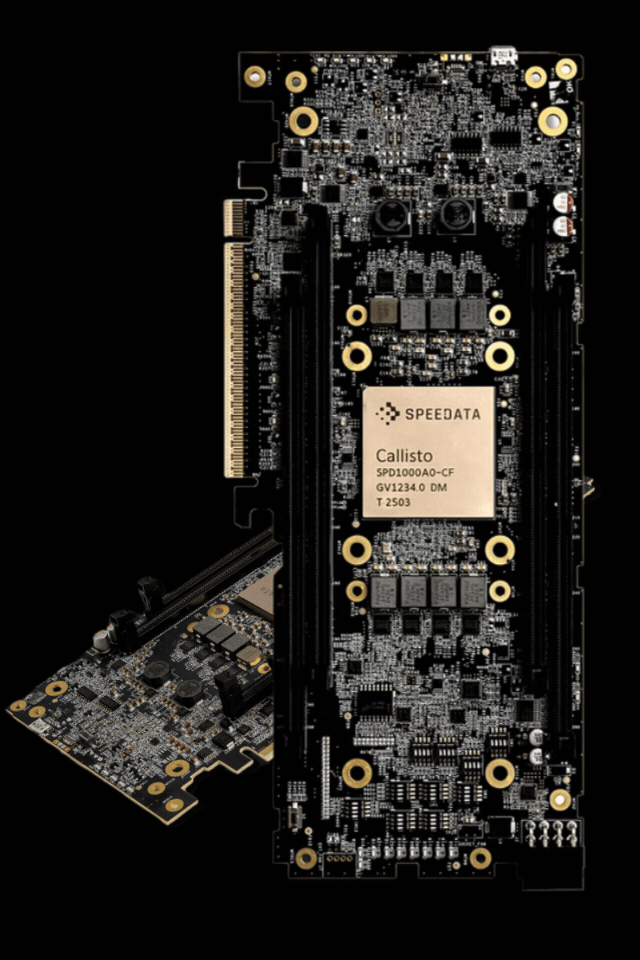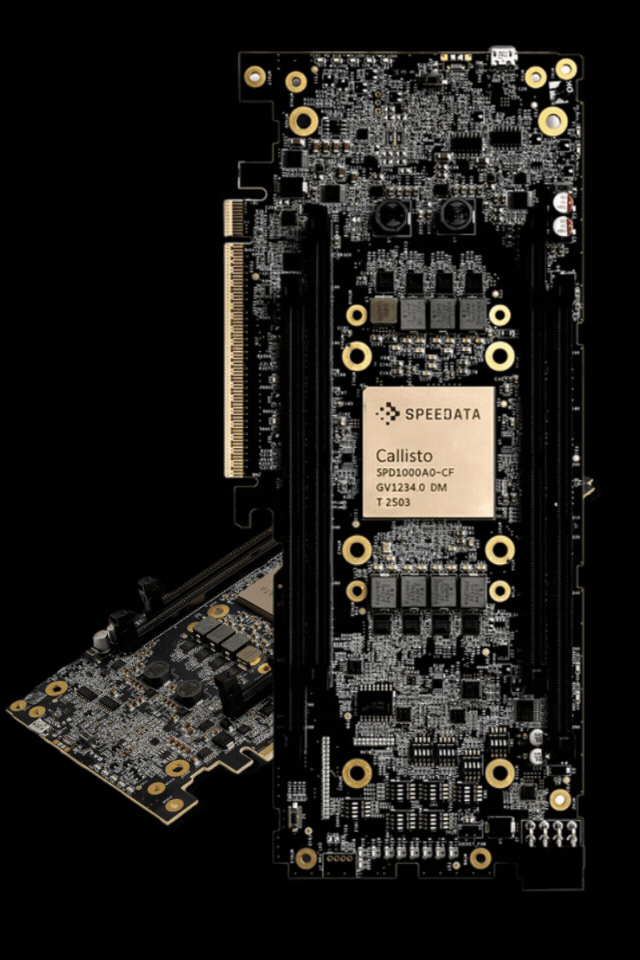
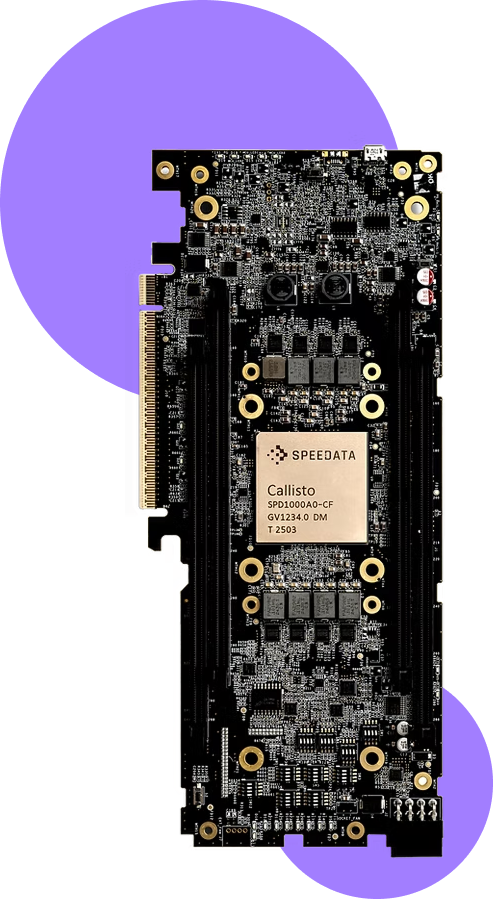
Speedata introduces a new class of compute: the Analytics Processing Unit (APU). A purpose-built hardware accelerator designed specifically to run Spark workloads faster, cheaper, and more efficiently at the silicon level.

Seamless integration with Apache Spark
Ready to accelerate Spark?
Speedata’s Dash software integrates directly with the Spark Catalyst optimizer and automatically detects and offloads compute intensive tasks to the APU. For SQL components that cannot be accelerated such as UDFs it seamlessly hands processing back to the CPU while continuing to execute the rest of the query ensuring consistently high performance.
Speedata works natively with Apache Spark, no code rewrite required.
Through the Dash software layer, Speedata plugs directly into Spark’s Catalyst optimizer.
How it works:
1) You run your Spark job as usual (SQL, DataFrame, ETL, etc.)
2) Dash automatically analyzes the query plan
3) Compute-intensive operations are offloaded to the APU
4) Non-acceleratable logic stays on CPU (e.g. UDFs)
5) Execution is transparently accelerated in hardware
Processes data directly in hardware pipelines. Up to 100x performance improvements on Spark workloads. Fewer nodes required.
Processes hundreds of rows in parallel at different stages and streams data through the chip continuously. Turn hours into minutes.
Eliminate CPU scheduling bottlenecks and avoids GPU memory transfer overhead. Reduce infrastructure costs.
Faster experimentation for data science and BI teams. Achieve extremely high throughput (billions of rows/sec class processing)
What makes it faster?
Speedata processes data using a streaming hardware pipeline architecture.
Instead of executing tasks sequentially like CPUs, it:
- Breaks query execution into hardware stages
- Processes hundreds of rows in parallel at different stages
- Streams data through the chip continuously
- Achieves extremely high throughput (billions of rows/sec class processing)

Eliminate CPU scheduling bottlenecks
Avoid GPU memory transfer overhead
Built for Spark SQL execution patterns
Why not just CPU or GPU?
1) CPUs
General-purpose, but not optimized for massive parallel analytics. Bottlenecks in joins, scans, and aggregations
High infrastructure cost per query.
2) GPUs
Excellent for AI/ML workloads.
But require data movement between CPU ↔ GPU memory
Often inefficient for SQL-heavy ETL pipelines. Not purpose-built for Spark query execution
3) Speedata APU (purpose-built)
Speedata is designed specifically for analytics workloads:
- Processes data directly in hardware pipelines
- Eliminates CPU scheduling bottlenecks
- Avoids GPU memory transfer overhead
- Built for Spark SQL execution patterns
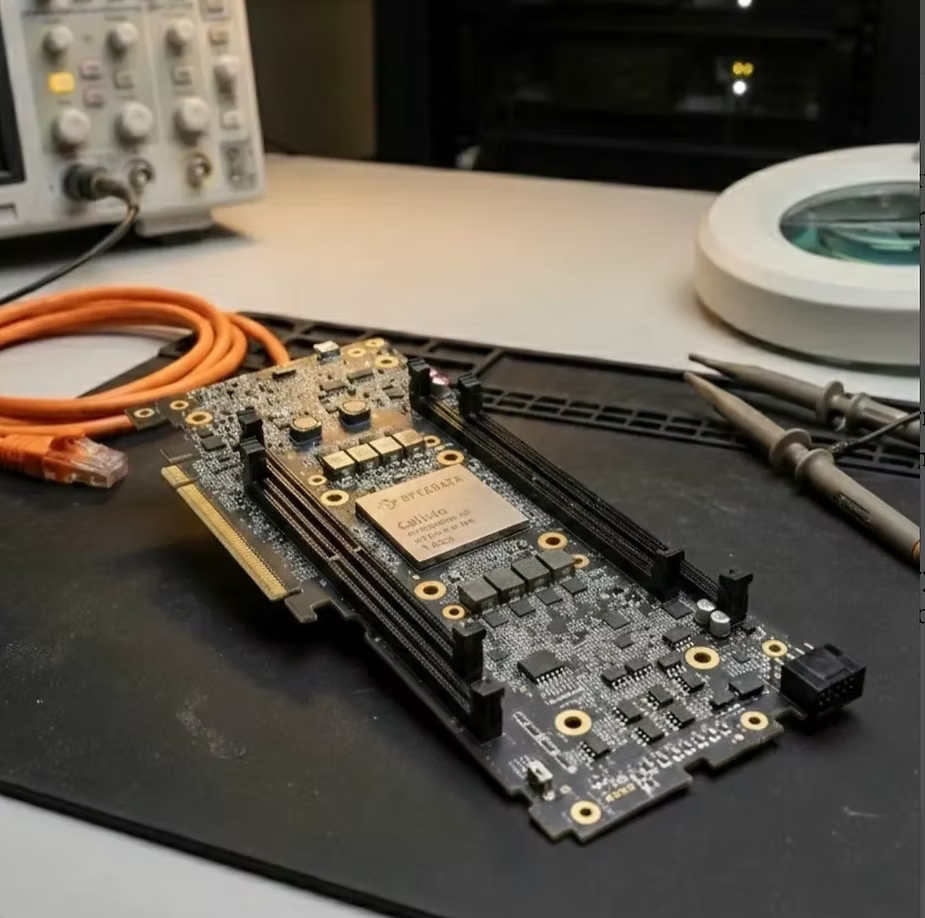
Get up to 100x performance improvements with APUs
Speedata – Data Analytics and AI Acceleration for Modern Data Centers
Speedata is an innovative technology manufacturer transforming the data center landscape with the world’s first purpose-built Analytics Processing Unit — APU. Designed to accelerate database analytics and AI workloads, Speedata’s solutions help enterprises process large volumes of data faster, more efficiently and with greater scalability.
The company combines advanced hardware and software into one powerful platform that integrates seamlessly with existing data ecosystems. Thanks to its massively parallel architecture, Speedata technology can deliver up to 100x performance gains in selected analytics workloads without requiring software changes.
Innovation Built on Experience and Precision
Speedata was founded on years of research and deep expertise in semiconductor innovation, software development and cloud infrastructure. Its approach is guided by core values such as boldness, discipline, creativity and integrity, supporting the development of reliable, scalable and future-ready technologies for demanding business environments.
Speedata Suppliers, Partner and Distributor — NGHS
As a technology partner, supplier and distributor, NGHS provides access to Speedata solutions for companies looking to improve data center performance, accelerate analytics, support AI processes and gain faster business insights. Through its cooperation with Speedata, NGHS helps organizations build more efficient, scalable and competitive IT infrastructure.
Ready to dicuss your next project?
Contact us
- Poland, Rybnik
- +48 880 992 280
- [email protected]
FAQ – Speedata APU for Data Analytics Acceleration
What is Speedata APU?
Speedata APU, or Analytics Processing Unit, is a purpose-built hardware accelerator created for demanding data analytics and AI data processing workloads. Unlike general-purpose CPUs or GPUs, it is designed to accelerate operations commonly used in Apache Spark SQL, batch ETL, Big Data processing, and AI data preparation. This makes it suitable for organizations that need faster analytical performance without completely redesigning their existing data pipelines.
Why choose Speedata APU for Apache Spark workloads?
Speedata APU is optimized for Apache Spark workloads that involve complex queries, joins, aggregations, transformations, and large-scale data processing. By executing selected Spark operations closer to the hardware level, the APU can help reduce processing time and improve the efficiency of analytics environments. This is especially important for companies that rely on Spark for business intelligence, data engineering, machine learning preparation, and large-scale reporting.
How can Speedata APU reduce analytics infrastructure costs?
Speedata APU can support cost reduction by improving the performance of analytics workloads and reducing the amount of general-purpose compute required for selected tasks. Faster processing may help organizations lower server usage, reduce energy demand, shorten job execution time, and improve infrastructure utilization. For businesses working with growing datasets, this can be an important step toward a more efficient and scalable data analytics architecture.
Which workloads can benefit from Speedata APU?
Speedata APU is designed for workloads such as Apache Spark SQL, batch ETL, data preparation, data cleaning, AI preprocessing, large-scale analytics, and structured data processing. It can be useful in environments where large volumes of data must be transformed, filtered, aggregated, or prepared before analysis or model training. Organizations using Big Data platforms, modern data lakes, analytics pipelines, or AI data workflows may benefit from this type of acceleration.
Is Speedata APU suitable for AI data preparation?
Yes. Speedata APU can support AI data preparation by accelerating the data processing layer that often sits before model training, inference, or generative AI workflows. Many AI projects require structured data to be cleaned, joined, filtered, transformed, and enriched before it can be used effectively. By improving the speed of these operations, Speedata APU can help teams move from raw data to usable AI-ready datasets more efficiently.
How does Speedata APU compare with CPU and GPU-based data processing?
CPUs are flexible general-purpose processors, while GPUs are often used for highly parallel workloads such as AI training and numerical computation. Speedata APU focuses specifically on analytics and structured data processing tasks. This specialization can make it valuable for organizations that need to accelerate Spark-based analytics, ETL pipelines, and data preparation workloads rather than relying only on traditional CPU or GPU infrastructure.
Can Speedata APU be integrated into existing data pipelines?
Speedata APU is designed to support integration with existing analytics environments and data processing pipelines. This is important for enterprises that want to improve performance without rebuilding their entire data architecture from the ground up. In many scenarios, the goal is to accelerate demanding Spark and ETL workloads while preserving familiar tools, established workflows, and existing operational processes.
What is the Speedata C200 analytics accelerator?
The Speedata C200 is an analytics accelerator card that includes the Speedata APU chip and is designed for high-bandwidth data processing. It uses PCIe connectivity, which allows it to be deployed in standard server configurations. The C200 is intended for organizations that need hardware-level acceleration for analytics workloads, especially in environments based on Apache Spark, batch ETL, and large-scale structured data processing.
Which companies can benefit from Speedata APU?
Speedata APU can benefit enterprises, cloud providers, financial institutions, telecom operators, AI companies, data-driven software vendors, and organizations operating large-scale analytics platforms. It is particularly relevant for businesses that process high volumes of structured data and need better performance from Spark, ETL, reporting, or AI data preparation workflows. Companies facing rising infrastructure costs or slow analytics jobs may find this technology especially useful.
How can NGHS.eu support companies interested in Speedata APU?
NGHS.eu can support companies by helping them evaluate Speedata APU in the context of their analytics workloads, infrastructure goals, and performance requirements. This includes discussing use cases such as Apache Spark acceleration, batch ETL optimization, AI data preparation, and large-scale data processing. Working with a knowledgeable technology partner can simplify product selection, reduce implementation risk, and help organizations plan a more efficient analytics infrastructure.