
Apache Spark has become one of the most widely used engines for large-scale data processing, analytics, machine learning and ETL pipelines. It helps organizations process massive datasets across distributed clusters, but as data volumes continue to grow, software optimization alone is often not enough. Companies need faster execution, lower latency and better infrastructure efficiency. This is where an Apache Spark accelerator becomes an important part of modern data architecture.
An Apache Spark accelerator uses dedicated hardware or hardware-aware software to speed up selected Spark workloads. Instead of relying only on traditional CPU processing, organizations can use GPU, FPGA or other specialized acceleration platforms to improve performance in demanding big data environments. For companies building advanced analytics, AI, cybersecurity, telecom or data center infrastructure, the right Apache Spark hardware can directly affect speed, scalability and operational costs.
What is an Apache Spark accelerator?
An Apache Spark accelerator is a solution designed to improve the performance of Spark workloads by moving selected operations from general-purpose CPU processing to more efficient hardware resources. These operations may include SQL queries, DataFrame processing, machine learning pipelines, sorting, filtering, joins, aggregations, data transformation or large-scale analytics tasks.
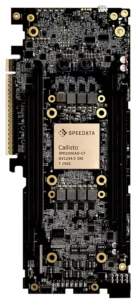
In practice, acceleration can be achieved in several ways. The most common approach is GPU acceleration, where Spark jobs use graphics processors for highly parallel data processing. Another option is FPGA acceleration, where programmable hardware can be configured for specific operations. In some environments, acceleration may also include optimized storage, high-speed networking, SmartNICs or dedicated data processing units.
The goal is not to replace Apache Spark, but to make Spark workloads run faster and more efficiently. A well-designed accelerator works as an additional performance layer inside the infrastructure.
Why Apache Spark needs hardware acceleration
Apache Spark is powerful, but it can become resource-intensive. Large datasets, frequent shuffle operations, complex joins, iterative machine learning tasks and heavy ETL workflows can put significant pressure on CPU, memory, storage and network resources.
In many organizations, the answer is simply to add more servers. This may improve capacity, but it also increases hardware costs, power consumption, licensing costs and maintenance complexity. Hardware acceleration offers a different strategy. Instead of scaling only by adding more CPU nodes, companies can improve the performance of selected workloads using specialized hardware.
This is especially important in environments where time matters. Financial analytics, fraud detection, AI model preparation, telecom data processing, log analysis and cybersecurity monitoring often require fast processing of large volumes of data. In these cases, an Apache Spark accelerator can help reduce execution time and make the entire data pipeline more responsive.
Apache Spark hardware – CPU, GPU, FPGA and dedicated accelerators
Choosing the right Apache Spark hardware depends on the workload. There is no single universal configuration that works best for every project. CPU-based clusters are flexible and reliable, but they may not be the most efficient option for highly parallel workloads. GPU and FPGA platforms can offer better performance for specific tasks, but they require proper planning and compatibility analysis.
CPU remains the foundation of most Spark environments. It handles general workloads, orchestration and many types of data processing. GPU is useful when the workload can benefit from parallel execution, especially in Spark SQL, DataFrame operations, machine learning and AI-related pipelines. FPGA is valuable when the infrastructure needs low-latency processing, custom logic or workload-specific acceleration.
Dedicated accelerators and SmartNICs may also play a role in modern data infrastructure. They can support networking, packet processing, data movement, compression, encryption or storage-related operations. This is relevant because Spark performance is not limited only by compute power. Network throughput, storage speed and data movement between nodes can also become major bottlenecks.
GPU acceleration for Apache Spark
GPU acceleration is currently one of the most practical ways to speed up selected Apache Spark workloads. Modern GPUs are designed for parallel processing, which makes them suitable for operations that can be executed across many data elements at the same time.
One well-known example is RAPIDS Accelerator for Apache Spark. It allows Spark applications to use GPUs for selected DataFrame and SQL operations. In many cases, organizations can run existing Spark workloads on GPUs with limited or no application code changes, depending on the supported operations and environment configuration.
GPU acceleration can be especially useful for ETL pipelines, analytics workflows, AI preparation, data science and large-scale query processing. It can also help improve infrastructure efficiency by reducing job execution time and enabling more work to be completed within the same operational window.
However, GPU acceleration should be evaluated carefully. Not every Spark workload will benefit equally. Small datasets, unsupported functions, excessive data transfer or poorly optimized pipelines may reduce the expected performance gains. Before investing in GPU-based Apache Spark hardware, companies should analyze their workload structure and identify which operations are suitable for acceleration.
FPGA acceleration in Apache Spark environments
FPGA acceleration is a more specialized but highly interesting approach. FPGA stands for Field-Programmable Gate Array. Unlike a fixed processor, FPGA can be programmed to perform selected operations directly in hardware. This makes it useful in scenarios where custom processing, low latency and predictable execution are important.
In Apache Spark environments, FPGA can be used to accelerate selected operators such as sorting, aggregation, filtering, machine learning algorithms or data movement. Research into CPU+FPGA architectures has shown that FPGA-based acceleration can support typical Spark operators, including K-means, PageRank and sorting. This makes FPGA relevant for advanced big data projects where standard CPU processing is not efficient enough.
FPGA is not always the first choice for general Spark acceleration. It usually requires more engineering effort than GPU-based acceleration. However, it can offer strong advantages in custom infrastructure, telecom, cybersecurity, edge computing, high-performance analytics and environments where programmable hardware is already part of the architecture.
For companies that need flexible acceleration and infrastructure tailored to specific workloads, FPGA-based Apache Spark hardware can be a strategic option.
How hardware acceleration improves Spark performance
Hardware acceleration improves Spark performance by reducing the amount of work performed by the CPU and moving suitable operations to more efficient hardware. This can lead to shorter job execution times, lower latency and better resource utilization.
For example, GPU acceleration can process parallel analytical operations faster than CPU-only execution. FPGA can support custom logic with predictable performance. High-speed networking and SmartNICs can reduce bottlenecks in distributed environments where large volumes of data must move between nodes.
In Spark clusters, performance depends on several layers at once: compute, memory, storage, network and software configuration. A strong accelerator strategy looks at the full system instead of focusing on only one component. In some cases, the biggest improvement may come from GPU acceleration. In others, the real bottleneck may be data transfer, storage throughput or network latency.
This is why Apache Spark hardware should be selected based on actual workload behavior, not only on theoretical performance specifications.
When should companies use an Apache Spark accelerator?
An Apache Spark accelerator is worth considering when Spark jobs take too long, infrastructure costs are rising or existing clusters cannot handle growing data volumes efficiently. It is also useful when the company needs faster analytics, shorter ETL windows or better support for machine learning and AI workloads.
Acceleration is particularly relevant for organizations that process large datasets every day. This includes data centers, cloud platforms, telecom operators, cybersecurity companies, financial institutions, research organizations and enterprises building AI-driven services.
A company should also consider acceleration when scaling by adding more CPU servers becomes too expensive or inefficient. In this situation, GPU, FPGA or dedicated acceleration hardware may help improve performance without simply expanding the cluster in a traditional way.
Key benefits of Apache Spark acceleration
The main benefit of Apache Spark acceleration is faster data processing. Shorter execution time can improve reporting, analytics, model training and business decision-making. In many organizations, reducing a job from hours to minutes can have a direct operational impact.
Another benefit is infrastructure efficiency. If accelerated hardware allows the same workload to run on fewer resources or complete faster, it may reduce operational costs. This includes server usage, energy consumption and cluster maintenance.
Apache Spark acceleration can also improve scalability. As datasets grow, companies need infrastructure that can handle more data without becoming unstable or excessively expensive. Accelerated hardware gives organizations more options when planning future capacity.
There is also a strategic benefit. Companies that invest in accelerated analytics infrastructure are better prepared for AI, real-time analytics, advanced monitoring and modern data applications.
Apache Spark accelerator and modern data infrastructure
Modern data infrastructure is no longer based only on general-purpose servers. Today, organizations combine CPUs, GPUs, FPGAs, SmartNICs, high-speed storage and advanced networking to create systems optimized for specific workloads.
Apache Spark fits naturally into this trend. It remains a powerful distributed data processing engine, but its performance depends on the quality of the underlying infrastructure. An Apache Spark accelerator helps organizations unlock more value from their data platforms by using hardware more intelligently.
This does not mean that every company needs the most advanced accelerator immediately. The right approach is to start with workload analysis. Which jobs are the slowest? Which operations consume the most resources? Is the bottleneck in compute, memory, storage or network? Once these questions are answered, it becomes easier to choose the right Apache Spark hardware.
Choosing the right Apache Spark hardware
Selecting Apache Spark hardware requires a balance between performance, flexibility, cost and long-term infrastructure strategy. GPU-based systems may be the best option for parallel data processing and AI-related workloads. FPGA-based platforms may be better for custom acceleration, low-latency processing and specialized infrastructure. CPU-only clusters may still be suitable for general-purpose workloads where acceleration would not bring enough value.
Companies should also consider compatibility with their software stack, data formats, orchestration tools and cloud or on-premise architecture. The best hardware accelerator is not just the fastest device on paper. It is the solution that works efficiently with the existing data pipeline and supports future business requirements.
For organizations planning high-performance analytics, AI, telecom, cybersecurity or data center projects, Apache Spark acceleration can become an important competitive advantage.
Conclusion
Apache Spark is a strong foundation for big data processing, but growing workloads require more than standard CPU-based scaling. An Apache Spark accelerator can help companies improve performance, reduce latency and build more efficient data infrastructure.
GPU acceleration is already a practical option for many Spark SQL, DataFrame and AI workloads. FPGA acceleration offers additional flexibility for specialized and low-latency use cases. Together with optimized networking, storage and data center hardware, these technologies help organizations process data faster and more intelligently.
For businesses that want to improve Spark performance, choosing the right Apache Spark hardware is a strategic infrastructure decision. NGHS.eu supports companies in selecting advanced networking, acceleration and data center solutions for demanding big data, analytics and high-performance computing environments.
An Apache Spark accelerator is a hardware or software-hardware solution designed to improve the performance of Spark workloads. It can use GPU, FPGA or other dedicated hardware to speed up selected operations such as SQL queries, DataFrame processing, ETL, sorting, filtering, aggregations and machine learning tasks.
Apache Spark hardware has a direct impact on processing speed, scalability and infrastructure costs. Spark workloads often depend on CPU power, memory capacity, storage speed and network throughput. Choosing the right hardware helps reduce bottlenecks and improves the efficiency of big data processing.
GPU acceleration helps Apache Spark by moving highly parallel operations from the CPU to the GPU. This can improve performance in Spark SQL, DataFrame operations, analytics, AI and machine learning workflows. It is especially useful for large datasets and repetitive analytical tasks.
Yes. FPGA can be used to accelerate selected Apache Spark operations, especially in specialized environments. FPGA hardware can be programmed for specific tasks such as sorting, filtering, aggregation or low-latency data processing. It is most useful where custom acceleration and predictable performance are required.
No. An Apache Spark accelerator is not always necessary. For smaller datasets or standard workloads, a CPU-based Spark cluster may be enough. Acceleration is most valuable when Spark jobs are slow, data volumes are large, latency matters or infrastructure costs are increasing.
The workloads that benefit most include large-scale ETL pipelines, Spark SQL queries, DataFrame processing, machine learning, AI data preparation, log analytics, financial analytics, cybersecurity monitoring and telecom data processing. The final performance gain depends on the workload structure and hardware configuration.
CPU is flexible and suitable for general-purpose Spark workloads. GPU is strong in parallel processing and can accelerate analytics, SQL and AI-related operations. FPGA is programmable hardware that can be optimized for specific tasks, low-latency processing and custom infrastructure requirements.
It can reduce infrastructure costs in some cases. If acceleration shortens job execution time or allows more work to be processed with fewer resources, it may improve cost efficiency. However, the final result depends on the workload, hardware price, energy use and implementation model.
A company should consider Apache Spark hardware acceleration when Spark jobs take too long, clusters are overloaded, reporting windows are too short, AI workloads are growing or adding more CPU servers becomes too expensive. It is also useful for organizations building advanced data center, cloud, telecom or cybersecurity infrastructure.
The right Apache Spark accelerator should be selected based on workload analysis. Companies should check whether the main bottleneck is compute, memory, storage, network or data movement. GPU may be the best option for parallel analytics and AI workloads, while FPGA may be better for specialized, low-latency or custom processing tasks.